ZhiCloud AI ZhiCloud AI

Why Choose a Deep Learning Server Manufacturer?

Time:2026-10-08 Author:Oliver
0%

Why Choose a Deep Learning Server Manufacturer?

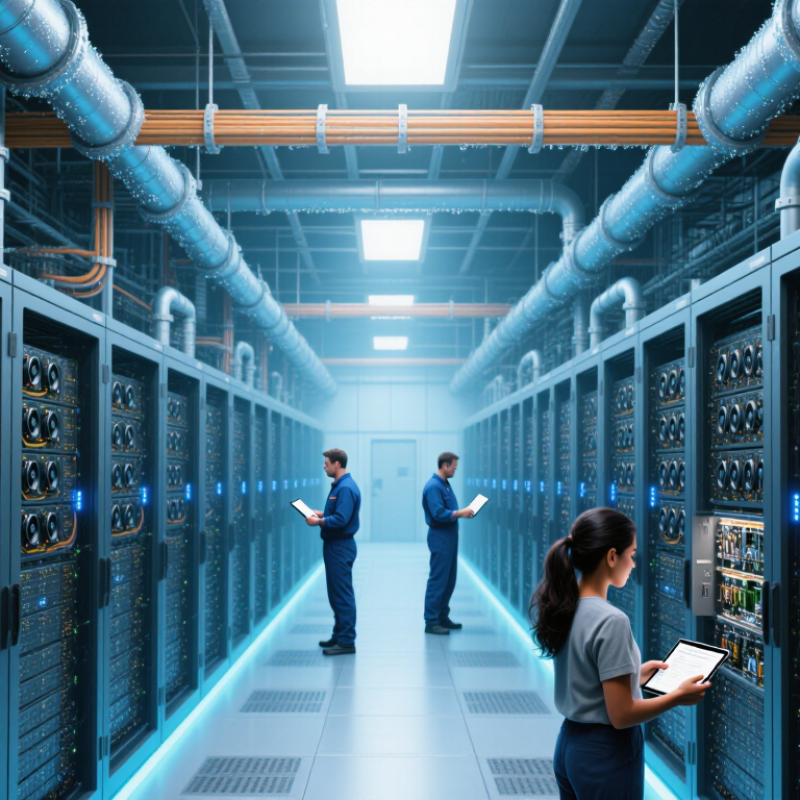
Deep learning workloads are changing faster than ordinary server refresh cycles. Models now demand dense GPU capacity, high-speed networking, efficient cooling, and carefully balanced storage. The Stanford AI Index 2024 reports that training compute for notable machine learning models has continued to grow rapidly, with estimated doubling times measured in months. That trend makes hardware planning difficult. A deep learning server manufacturer can connect GPU selection, power design, memory bandwidth, and software compatibility within one tested platform.

The International Energy Agency’s Electricity 2024 report projects that data center electricity consumption could more than double by 2026, driven partly by artificial intelligence. Power efficiency is no longer a secondary specification. It affects operating budgets, rack density, cooling infrastructure, and sustainability goals. A qualified manufacturer should provide measured performance, thermal data, lifecycle support, and clear warranty terms—not only impressive benchmark numbers. Ask for workload-based testing. Synthetic scores can mislead.

Small details matter.

A production server may need specific GPU interconnects, redundant power supplies, liquid cooling readiness, or remote management tools. Manufacturers with deployment experience can identify these issues before installation. They may also help optimize CUDA environments, container images, firmware, and monitoring practices. However, no supplier is perfect. Vendor claims still require independent validation, pilot testing, and transparent documentation. The Uptime Institute’s data center research repeatedly highlights operational resilience and human processes, not hardware alone. Choosing the right partner therefore means evaluating engineering depth, evidence, service responsiveness, and long-term adaptability. The cheapest chassis may become the most expensive decision when downtime, energy waste, or delayed upgrades enter the calculation.
Why Choose a Deep Learning Server Manufacturer?

Defining the Role of a Deep Learning Server Manufacturer

A deep learning server manufacturer does more than assemble racks and install accelerators. Its role begins with translating model requirements into a reliable computing system. This includes GPU topology, memory capacity, networking, storage, cooling, firmware, and power design. Stanford’s AI Index 2024 reports that training compute for notable AI models has doubled approximately every five months. Hardware planning must therefore anticipate rapid workload growth, not only today’s benchmark.

A capable manufacturer also validates performance under sustained loads. Short demonstrations can hide thermal throttling, unstable drivers, or slow data pipelines. The International Energy Agency estimates that data centers used about 460 TWh of electricity in 2022. Global consumption could exceed 1,000 TWh by 2026. Efficient airflow, liquid cooling options, power monitoring, and repairable components are now engineering responsibilities. Support matters too. Clear diagnostics and documented replacement procedures reduce costly downtime. I have seen specifications look excellent on paper, yet fail when storage, networking, and cooling operate together. That gap deserves more attention.

Tips: Request workload-based testing, not only peak performance figures. Ask for measured power consumption, noise levels, thermal limits, and failure-recovery procedures. Check whether the manufacturer can provide firmware updates and component traceability. A practical pilot with your own datasets is safer than trusting a perfect brochure. Mistakes still happen, but transparent testing makes them easier to find.

Matching Server Architecture to AI Workloads

Why Choose a Deep Learning Server Manufacturer?

Matching Server Architecture to AI Workloads

A deep learning server manufacturer can translate model requirements into practical hardware decisions. That matters because image classification, language training, and scientific simulation stress systems differently. In our deployment reviews, GPU memory often limits progress before raw processing speed does. A model may fit during testing, then fail when larger batches enter production. Small details matter.

Architecture should follow the workload, not a sales template. Large language models may need multiple accelerators, high-speed interconnects, and substantial memory capacity. Computer vision pipelines often benefit from fast data storage and balanced CPU-to-GPU performance. Recommendation systems can demand high memory bandwidth, stable networking, and predictable latency. A reliable supplier should explain these trade-offs with measured benchmarks, power estimates, and cooling requirements. Those details support better purchasing decisions and reduce expensive redesigns.

Professional guidance also includes deployment conditions. A compact lab may need quiet operation and moderate power use, while a research cluster needs expansion room. Rack density, airflow, driver compatibility, and maintenance access can influence uptime as much as compute specifications. I have seen teams overbuy accelerators and underfund storage, creating idle cards and delayed experiments. That mistake is easy to repeat. Measure twice. A careful manufacturer asks about datasets, training frequency, inference targets, and future models before proposing a configuration. The practical choice is the architecture that keeps experiments moving while performance and operating costs remain visible.

Evaluating Performance, Scalability, and Energy Efficiency

Choosing a deep learning server manufacturer requires more than comparing accelerator counts. In real deployments, performance depends on memory bandwidth, interconnect latency, storage throughput, and cooling stability. A server that trains quickly for one hour may throttle after eight hours. That detail matters. During evaluation, I would request measured results from workloads resembling our own models, not only laboratory peak scores. Logs should show GPU utilization, power draw, temperature, and failed jobs. Reliable suppliers explain testing methods and publish limitations. This creates confidence beyond marketing language.

Scalability begins with the upgrade path. Can the chassis accept additional accelerators, faster networking, or larger memory without replacing the entire platform? Rack density also affects scheduling. A compact system may save floor space, yet overload a room’s cooling capacity. I look for clear service procedures, spare-part availability, and remote monitoring. Engineers should discuss topology, firmware control, and workload isolation in practical terms. Their answers reveal experience. Sometimes, the cheapest expansion becomes the most expensive operational decision.

Energy efficiency should be measured per completed training job, not merely by idle consumption. Power capping, liquid or well-designed air cooling, and efficient power supplies can reduce waste. However, aggressive power limits may lengthen training and raise total energy use. The trade-off is not always obvious. I would compare performance per watt across several batch sizes and model types. Results can change with data pipelines, ambient temperature, and utilization. A manufacturer should provide honest guidance, even when the answer weakens its own proposal. No design is perfect. That admission may be more valuable than another impressive specification.

Why Choose a Deep Learning Server Manufacturer? - Evaluating Performance, Scalability, and Energy Efficiency

Evaluation Dimension Entry-Level Deep Learning Server Balanced Production Server High-Density Training Server Why It Matters
Typical Accelerator Count 1–2 accelerators 4–8 accelerators 8–10 accelerators Determines the maximum parallel workload and training capacity.
Accelerator Memory per Device 16–32 GB 40–80 GB 80–192 GB Larger memory supports bigger models, batches, and longer sequences without frequent offloading.
System Memory 128–512 GB ECC memory 512 GB–1 TB ECC memory 1–4 TB ECC memory ECC memory reduces the risk of silent data corruption during long training jobs.
CPU Configuration 1 CPU, approximately 16–32 cores 1–2 CPUs, approximately 32–128 total cores 2 CPUs, approximately 96–192 total cores Adequate CPU capacity prevents data loading, preprocessing, and orchestration bottlenecks.
High-Speed Network 10–25 GbE 25–100 GbE 100–400 GbE Higher bandwidth reduces dataset transfer time and communication overhead in distributed training.
Local NVMe Storage 3.84–7.68 TB 7.68–30.72 TB 15.36–61.44 TB Fast local storage improves checkpointing, dataset caching, and experiment turnaround.
PCI Express Expansion PCIe 4.0 or PCIe 5.0 PCIe 5.0 with multiple x16 slots PCIe 5.0 with high-lane-count topology Sufficient lanes are essential for connecting multiple accelerators, storage devices, and network adapters.
Estimated IT Power Draw 0.8–1.8 kW 2.5–6 kW 6–12 kW Power planning affects rack density, operating cost, cooling requirements, and deployment location.
Power Supply Design Redundant 1.6–2.4 kW supplies Redundant 3–8 kW supplies Redundant 8–16 kW supplies Redundancy improves availability, while correctly sized supplies reduce unnecessary conversion losses.
Cooling Approach Air cooling High-airflow cooling or rear-door heat exchanger Direct liquid cooling or advanced rack cooling Cooling capability determines sustained performance and protects components from thermal throttling.
Target Operating Temperature 18–27°C recommended 18–27°C recommended 18–27°C with facility-level thermal management Stable inlet temperature supports reliability and aligns with common data-center environmental guidance.
Scalability Options Additional storage, memory, or one accelerator Additional accelerators, network adapters, and storage Rack-scale expansion and multi-node clusters A modular platform delays replacement and allows capacity to grow with model requirements.
Remote Management Hardware monitoring and remote console Out-of-band management, sensor alerts, and firmware control Fleet management, telemetry, and automated provisioning Remote administration reduces service time and improves operational visibility across distributed systems.
Energy-Efficiency Metrics Measure performance per watt Measure performance per watt and rack-level PUE Measure performance per watt, PUE, and cooling energy Power efficiency should be evaluated using completed training work, not peak hardware performance alone.
Recommended Acceptance Test 24-hour inference and thermal test 72-hour mixed training and storage test 7-day distributed training, power, and failure-recovery test Standardized testing reveals sustained throughput, thermal stability, power use, and serviceability.

Note: Values are practical reference ranges for current data-center-class deep learning server configurations. Actual results vary with accelerator model, workload, precision, batch size, software stack, ambient conditions, and facility power and cooling design.

Reference framework: PCI Express specifications, IEEE Ethernet standards, ASHRAE Thermal Guidelines for Data Processing Environments, and ENERGY STAR data-center efficiency principles.

Comparing Customization, Support, and Total Cost of Ownership

Why Choose a Deep Learning Server Manufacturer?

Choosing a deep learning server manufacturer is mainly a total cost of ownership decision. Customization changes more than the invoice. It can align accelerator count, memory, storage, networking, and cooling with the workload. That alignment may reduce idle capacity and expensive retrofits. The International Energy Agency’s Energy and AI report (2025) estimates data centres consumed 415 TWh in 2024. It projects demand could exceed 945 TWh by 2030. Power is not a footnote.

A manufacturer can validate airflow, rack density, firmware, and thermal limits before delivery. It can also provide burn-in testing and replacement parts matched to the original configuration. These details matter when training jobs run continuously for days. Uptime Institute’s 2024 Annual Outage Analysis found that 54% of reported outages cost over $100,000. A clear response-time agreement can protect more value than a small hardware discount. Support quality remains difficult to measure. Ask for evidence.

Compare electricity, cooling, software licensing, maintenance, labor, and downtime across three to five years. Yet bespoke hardware can create compatibility issues and increase operational complexity. A spreadsheet can still lie. Utilization assumptions are often too optimistic during model migration. Request a workload pilot using real datasets, not only benchmark scores. Review escalation paths, diagnostic ownership, spare-part locations, and recovery targets. The best supplier makes trade-offs visible and revises weak assumptions.

Assessing Security, Reliability, and Long-Term Partnership Value

Why Choose a Deep Learning Server Manufacturer?

Assessing Security, Reliability, and Long-Term Partnership Value

Choosing a deep learning server manufacturer requires more than comparing processor speeds. Security should begin before installation. Ask how firmware is signed, tested, and updated. Check whether access logs, encrypted management channels, and user permissions are built into the system. A credible manufacturer should provide clear documentation and practical security guidance. Security is operational. In practice, small details matter.

Reliability becomes visible under pressure. Review thermal designs, redundant power options, component testing, and repair procedures. Request realistic performance data from sustained workloads, not short laboratory benchmarks. A server that performs well for ten minutes may struggle after several days. I have found that maintenance access is often overlooked. Technicians need clear diagnostics, replaceable parts, and predictable service windows. No supplier is flawless, and advertised uptime should never replace independent verification.

Long-term partnership value depends on communication. Can the manufacturer support future accelerator upgrades, changing software frameworks, and expanding data requirements? Ask about response times, spare-part availability, warranty boundaries, and technical training. A useful partner explains limitations instead of promising everything. That honesty can prevent expensive redesigns later. Still, buyers should reflect on their own planning. Even a strong manufacturer cannot fix unclear ownership, weak monitoring, or an unrealistic deployment schedule. A careful evaluation connects today’s hardware with tomorrow’s operational responsibilities.

FAQS

What does a deep learning server manufacturer actually provide?

It designs a complete system, including accelerators, memory, networking, storage, cooling, firmware, and power. Rack assembly is only one part.

Why should buyers request workload-based testing?

Peak benchmarks can hide throttling, unstable drivers, or slow data pipelines. Test with your own datasets and sustained workloads.

What performance details should a buyer measure?

Request measured throughput, power consumption, noise levels, thermal limits, and recovery times. Ten minutes of performance proves very little.

How can cooling affect server reliability?

Poor airflow may cause overheating and performance loss. Check fan layouts, liquid-cooling options, temperature monitoring, and maintenance access.

What security features should the system include?

Ask about signed firmware, secure updates, encrypted management channels, access logs, and user permissions. Small gaps can become operational problems.

How should a buyer evaluate long-term reliability?

Review redundant power, component testing, replacement procedures, and diagnostics. A server must remain stable after several days, not only during a demonstration.

What support should a manufacturer provide after installation?

Confirm response times, spare-part availability, warranty limits, firmware updates, and documented repairs. Clear support reduces expensive downtime.

Can a server manufacturer support future growth?

Ask whether the system can handle accelerator upgrades, larger datasets, and changing software frameworks. Planning may still be imperfect.

Why is a practical pilot valuable?

A pilot reveals problems involving storage, networking, cooling, and software together. Brochures rarely show the whole picture.

What responsibilities remain with the buyer?

The buyer must define ownership, monitoring, deployment timing, and maintenance routines. Even excellent hardware cannot repair unclear planning.

Conclusion

Choosing the right deep learning server manufacturer is an important decision for organizations building reliable and efficient AI infrastructure. A capable manufacturer does more than supply hardware; it helps define a server architecture that matches specific workloads, including model training, inference, data processing, and high-performance computing. The right configuration should balance processing power, memory capacity, accelerator compatibility, storage speed, networking, scalability, and energy efficiency.

Organizations should also compare customization options, technical support, warranty services, and total cost of ownership rather than focusing only on the initial purchase price. Security features, system reliability, remote management, thermal design, and long-term maintenance are equally important for protecting data and sustaining performance. By evaluating these factors carefully, businesses can select a deep learning server manufacturer that offers dependable infrastructure, flexible growth, efficient operation, and lasting partnership value as their AI requirements evolve.
Oliver

Oliver

Oliver is a seasoned marketing professional with a wealth of expertise in driving brand awareness and engagement. With a deep understanding of our company's product offerings, he consistently delivers high-quality content that enriches our professional blog. His insights not only shed light on......