ZhiCloud AI ZhiCloud AI

2026 Best H100 Server Manufacturer for Global Buyers?

Time:2026-10-22 Author:Ethan
0%

Choosing the best h100 server manufacturer in 2026 requires more than comparing GPU counts and advertised prices. Global buyers need evidence of engineering experience, reliable delivery, thermal design, and long-term technical support. An H100 server may look impressive on a product page, yet fail under sustained workloads if airflow, power distribution, or firmware settings are poorly managed.

NVIDIA founder and CEO Jensen Huang said, “Generative AI is the most consequential platform shift in computing history.” His statement explains why H100 infrastructure deserves careful evaluation. These systems support demanding workloads, including model training, inference, scientific computing, and enterprise analytics. A qualified h100 server manufacturer should provide clear configuration details, such as SXM or PCIe architecture, NVLink capability, memory capacity, networking options, and rack-level power requirements. Buyers should also examine burn-in testing, remote management, spare-part availability, and response times across different regions.

The strongest suppliers usually show practical experience, not only polished specifications. Ask for deployment references, validation reports, and realistic delivery schedules. Check whether the manufacturer can support local installation and multilingual service teams. However, no supplier is perfect. A vendor may offer excellent hardware but weaker documentation. Another may provide fast support but limited customization. That is why this comparison considers both measurable performance and operational risk. The final choice should fit your workload, budget, data-center conditions, and growth plan. H100 technology is powerful, but careless procurement can make expensive equipment underperform.
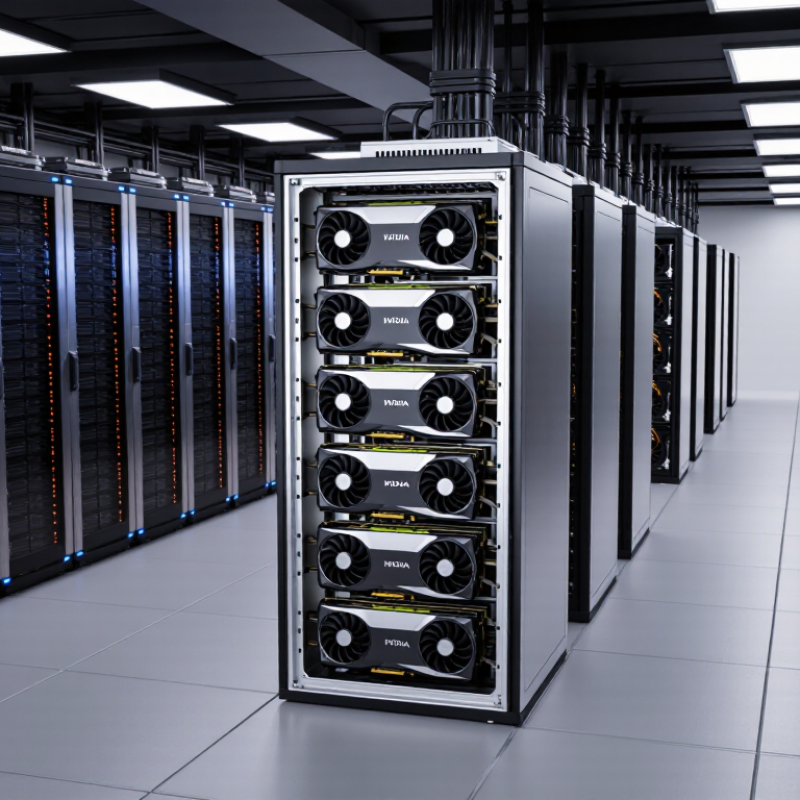
2026 Best H100 Server Manufacturer for Global Buyers?

H100 Server Basics and Core Architecture

H100 Server Basics and Core Architecture

An H100 server combines one or more data-center GPUs with host CPUs, memory, storage, and networking. Its core purpose is parallel computing for artificial intelligence, scientific workloads, and large-scale model training. That is the simple part. Real performance depends on how these components communicate.

The H100 GPU uses high-bandwidth HBM3 memory for rapid access to training data. A typical server may include four or eight GPUs, depending on its chassis and workload design. GPU-to-GPU communication can use high-speed links or switching fabrics. This reduces data movement through the CPU and improves distributed training efficiency. The CPU manages operating systems, data preparation, and application control. System memory supports these tasks, while PCIe connects GPUs, storage, and network adapters.

Bandwidth matters. Fast local storage helps prevent training pauses during dataset loading. Network adapters should match the required data-transfer speed and cluster design. Power delivery and cooling also shape dependable performance. Dense GPU systems can produce substantial heat, requiring carefully designed airflow or liquid cooling.

I have seen specification sheets that looked impressive but ignored rack power limits. That mistake becomes expensive during deployment.

Buyers should check GPU configuration, memory capacity, interconnect topology, firmware support, warranty response, and tested workload results. No design is perfect. Even experienced engineers can overvalue peak benchmark scores while underestimating maintenance access and long-term operating costs.

Key Criteria for Choosing an H100 Server Manufacturer

2026 Best H100 Server Manufacturer for Global Buyers?

Key Criteria for Choosing an H100 Server Manufacturer

Choosing an H100 server manufacturer requires more than comparing GPU counts and advertised prices. A reliable supplier should explain power design, cooling capacity, PCIe layout, and high-speed interconnect performance. Request detailed thermal reports, not only attractive benchmark charts. Rack density matters when each cabinet must support sustained workloads.

I would also examine manufacturing experience and deployment records. Ask whether the engineering team has handled multi-GPU training clusters, airflow balancing, firmware updates, and remote diagnostics. A strong manufacturer provides clear validation procedures before shipment. Burn-in testing, component traceability, and documented quality controls reduce unpleasant surprises. Small details matter.

Support can decide whether a powerful server becomes a useful business tool. Check response times, spare-parts availability, warranty boundaries, and technician coverage in your region. Global buyers should review shipping documents, electrical standards, data protection practices, and lawful procurement requirements. Do not accept vague promises. Specifications can look perfect on paper, yet fail under continuous load. I have seen one overlooked cable or cooling assumption delay an entire deployment. No manufacturer is flawless, so ask how failures are reported, corrected, and prevented from recurring. A transparent answer often reveals more than a polished sales presentation.

Suggested procurement weighting for comparing H100 server manufacturers. The priorities emphasize reliable GPU integration, thermal and power design, high-speed networking, service capability, and total operating cost rather than brand reputation alone.

Leading H100 Server Manufacturing and Supply Capabilities

2026 Best H100 Server Manufacturer for Global Buyers?

Leading H100 server manufacturing depends on more than GPU availability. Reliable suppliers must control chassis design, thermal testing, firmware integration, and international logistics. Each server should pass burn-in testing before shipment. That matters.

The International Energy Agency estimates global data center electricity use could exceed 1,000 TWh annually by 2026. Therefore, H100 platforms need efficient airflow, high-capacity power delivery, and practical liquid-cooling options. The Uptime Institute’s 2024 Global Data Center Survey reported an average facility PUE of about 1.56. Manufacturing teams should consider these efficiency pressures during rack planning, not after installation.

Strong supply capability also requires traceable components, documented quality procedures, and regional technical support. A capable manufacturer can provide configurable node counts, redundant power systems, and validated networking layouts. It should also disclose testing methods and realistic lead times. Some suppliers still publish impressive specifications without explaining thermal limits. That deserves scrutiny. Buyers should request factory acceptance records, failure-rate data, spare-part policies, and deployment references. The details can feel inconvenient, but they often reveal whether production is repeatable or merely opportunistic. Global buyers also need packaging designed for long-distance transport, customs documentation, and service procedures that local engineers can follow. A perfect factory promise is not enough. Reliability begins with evidence.

2026 Best H100 Server Manufacturer for Global Buyers? - Leading H100 Server Manufacturing and Supply Capabilities
Capability Dimension Reference Requirement for Global Buyers H100 Server Manufacturing Benchmark Recommended Acceptance Evidence Procurement Importance
Supported Accelerator Form Factors Support both PCIe-based and SXM-based H100 server designs where applicable. PCIe configurations commonly use 80 GB HBM3 accelerators; SXM configurations commonly use 80 GB HBM3 accelerators with high-speed GPU interconnect capability. Validated bill of materials, accelerator compatibility matrix, and system-level qualification report. High
GPU Density Options Offer scalable platforms for development, inference, training, and high-performance computing. Typical designs include 1, 2, 4, or 8 accelerator configurations, depending on chassis, cooling, motherboard, and interconnect topology. System drawings, PCIe lane map, GPU placement diagram, and validated maximum-GPU configuration. High
GPU Memory Capacity Provide sufficient high-bandwidth memory for large-model training and inference workloads. Common H100 configurations provide 80 GB of HBM3 memory per accelerator; total memory scales with the number of installed accelerators but is not automatically pooled across GPUs. Accelerator identification report and operating-system-level memory verification. High
Host Expansion Interface Use current-generation host connectivity for high-throughput data movement. PCIe Gen5 connectivity is required for many H100 PCIe server designs; the exact number of lanes depends on the CPU, motherboard, retimers, storage, and network adapters. Motherboard block diagram, PCIe topology report, and link-speed validation under load. High
GPU-to-GPU Interconnect Provide an appropriate interconnect for multi-GPU communication. SXM-based systems can use high-bandwidth GPU interconnect technology; PCIe-based systems normally rely on PCIe unless an additional supported interconnect architecture is included. Topology diagram, bandwidth test results, and multi-GPU collective communication benchmark. High
Server Form Factor Match the deployment environment and rack-density plan. Single-server designs commonly range from 1U to 4U or larger, with 4U platforms frequently used for dense eight-accelerator configurations. Mechanical drawing, rack-unit specification, rail-kit details, and service-clearance requirements. Medium
Power Delivery Maintain stable power under sustained accelerator workload. System power depends on GPU count, CPU selection, memory, storage, networking, and fan speed. An 8-accelerator platform requires substantially more power capacity than a 1- or 2-accelerator platform. Power-budget worksheet, redundant power-supply specification, input-voltage range, and full-load power test. High
Thermal Management Prevent thermal throttling during continuous training and inference. Qualified designs should include high-static-pressure fan assemblies, controlled airflow paths, GPU temperature monitoring, and a defined ambient operating range. Thermal test report at sustained load, fan-control profile, inlet-temperature limit, and throttling record. High
CPU and Memory Balance Avoid host-side bottlenecks when feeding multiple accelerators. Multi-GPU systems should provide sufficient CPU PCIe resources and system memory. The final balance depends on workload, storage bandwidth, network traffic, and data-loader design. CPU-to-GPU affinity map, NUMA topology, memory population guide, and workload benchmark. High
System Memory Expandability Support large datasets, preprocessing, caching, and virtualization requirements. Use a server platform with adequate memory channels and validated DIMM capacity; the supported maximum depends on the processor generation and motherboard design. Qualified memory list, maximum-capacity statement, memory stress-test result, and ECC verification. Medium
Storage Configuration Provide fast local storage for datasets, checkpoints, containers, and logs. Typical designs combine boot storage with enterprise NVMe storage; the number of drives depends on available PCIe lanes, backplane design, and thermal limits. Drive-bay layout, supported NVMe list, sequential-read/write test, and RAID or software-storage configuration. Medium
High-Speed Networking Support distributed training, shared storage, and cluster management. Qualified systems may include high-speed Ethernet or InfiniBand-class adapters, subject to available PCIe lanes, transceiver compatibility, and fabric design. Network adapter qualification, port-speed test, firmware matrix, and cluster communication benchmark. High
Firmware and Software Validation Deliver a reproducible software stack for production deployment. Validation should cover system firmware, accelerator firmware, driver compatibility, container runtime, monitoring tools, and the selected operating system. Version-controlled compatibility matrix, installation guide, image checksum, and clean-install procedure. High
Factory Testing Detect hardware faults before international shipment. Testing should include memory diagnostics, storage tests, network tests, accelerator enumeration, multi-GPU stress, thermal validation, and power-cycle testing. Serial-number-linked factory test report and recorded results for every shipped system. High
Burn-In Capability Reduce early-life failures in continuous-use environments. A suitable process uses sustained CPU, memory, storage, networking, and multi-GPU workloads rather than relying only on a short boot test. Burn-in duration, workload description, temperature log, error log, and failure-replacement procedure. High
Customization Capability Adapt the server to regional power, rack, networking, storage, and workload requirements. Preferred suppliers can configure accelerator count, memory, storage, network adapters, power cords, rail kits, firmware, and operating-system images without changing the validated platform design. Configurable bill of materials, engineering-change process, and pre-shipment configuration checklist. Medium
International Shipping Readiness Support customs clearance and deployment across multiple regions. Export-ready packaging should include shock and tilt protection, moisture control, clear serial-number labeling, commercial documentation, and region-appropriate power accessories. Packing specification, carton dimensions and weight, export documents, and damage-claim process. Medium
Warranty and Spare Parts Minimize downtime after deployment. A production-oriented supplier should define warranty duration, response targets, replacement procedures, spare-fan and power-supply availability, and escalation contacts. Written warranty terms, service-level agreement, spare-parts list, and return-material authorization process. High
Supply Continuity Maintain predictable delivery for pilot and volume orders. Reliable planning requires allocation confirmation, component lead-time visibility, configuration freeze dates, and a documented substitution policy. Production schedule, allocation statement, lead-time assumptions, and change-notification commitment. High
Acceptance Benchmark Verify that delivered systems meet the purchased specification. Acceptance should confirm accelerator count, memory size, link state, GPU health, thermal behavior, storage performance, network performance, and error-free stress testing. Customer acceptance test plan with measurable pass/fail thresholds and signed test records. High
Reference basis: H100 technical characteristics, PCIe Gen5 platform requirements, enterprise server qualification practices, and standard data-center procurement criteria. Actual performance, power consumption, delivery time, and supported configurations must be confirmed in the supplier’s current quotation and validation documents.

Global Buyer Considerations: Pricing, Delivery, and Support

2026 Best H100 Server Manufacturer for Global Buyers?

For global buyers, pricing is only the opening question. A serious quotation should show GPU configuration, memory, networking, power supplies, shipping terms, and warranty coverage. Ask whether installation testing is included. Hidden costs often appear after approval.

Delivery reliability matters when a project depends on strict deployment dates. Request a written production schedule, packing details, and tracking milestones. Confirm the shipping method and responsibility for customs documents. A reliable manufacturer should explain regional voltage requirements and provide clear export paperwork. Delays still happen. Our early estimates were sometimes too optimistic, especially during component shortages.

Support can protect a large investment. Look for remote diagnostics, response-time commitments, spare-part access, and trained technical staff. Ask how faults are handled across time zones. A useful support team should understand rack density, cooling limits, firmware updates, and cluster integration. Test their answers before ordering. Send practical questions, not only sales inquiries.

A lower price may reflect fewer services. It may also reflect a genuine efficiency advantage. Compare complete ownership costs over three years, including energy, maintenance, freight, and downtime. Request customer references from similar regions and workloads. Clear communication is evidence of professionalism, but it is not proof. Verify every promise in writing.

H100 Server Deployment, Maintenance, and Future Scalability

2026 Best H100 Server Manufacturer for Global Buyers?

H100 Server Deployment, Maintenance, and Future Scalability

A dependable H100 deployment starts with site readiness, not a purchase order. Each accelerator may require up to 700 watts, creating serious rack-level heat. Buyers should verify power redundancy, cooling capacity, airflow paths, and network bandwidth before delivery. A rack diagram is not a deployment plan. Acceptance testing should include thermal checks, GPU diagnostics, fabric latency, and workload validation.

Maintenance needs equal attention. Uptime Institute’s 2024 Global Data Center Survey reported that 53% of operators experienced an outage within the previous three years. Spare power modules, fans, cables, and tested replacement procedures can reduce recovery delays. Monitoring should track temperature, power draw, memory errors, and performance drift. Small warning signals matter. However, maintenance plans often overlook technician training and local parts availability.

Scalability must include energy planning. The International Energy Agency’s Energy and AI report estimates that data centers used about 415 TWh of electricity in 2024. Demand could approach 945 TWh by 2030. Future expansion may require liquid cooling, higher-capacity power distribution, and redesigned server rooms. Retrofitting is possible, but it is rarely simple. Some buyers still scale compute first and utilities later, which creates expensive constraints. A practical roadmap should reserve rack space, cooling headroom, network ports, and maintenance access from day one.

FAQS

What should buyers compare when choosing an H100 server manufacturer?

Compare power design, cooling capacity, PCIe layout, networking, and sustained workload performance. GPU count alone is not enough. Ask for thermal reports, not just benchmark charts.

Why does rack density matter for H100 servers?

Each accelerator can require up to 700 watts. Several units create intense heat inside one cabinet. Check power redundancy, airflow paths, and cooling headroom before delivery.

What testing should happen before shipment?

Request burn-in testing, component traceability, firmware checks, and documented quality controls. Acceptance testing should include thermal readings, GPU diagnostics, and network latency. Details matter.

How can buyers evaluate technical support?

Ask about response times, remote diagnostics, spare parts, warranty limits, and regional technician coverage. Test support with practical questions before ordering. Sales replies are not proof.

What costs should a complete quotation include?

The quotation should list GPUs, memory, networking, power supplies, shipping, installation testing, and warranty coverage. Compare three-year ownership costs. Include energy, maintenance, freight, and downtime.

How can international buyers reduce delivery problems?

Request a written production schedule, packing details, tracking milestones, and export documents. Confirm voltage requirements and customs responsibilities. Early delivery estimates can be too optimistic.

What maintenance plan is suitable for a high-density server rack?

Monitor temperature, power draw, memory errors, and performance drift. Keep spare fans, power modules, and cables nearby. Technician training and local parts availability are sometimes overlooked.

How should buyers plan for future expansion?

Reserve rack space, cooling capacity, network ports, and maintenance access from day one. Future growth may require liquid cooling and stronger power distribution. Retrofitting is rarely simple.

What warning signs suggest a manufacturer may be unreliable?

Be cautious when specifications are vague or failure procedures are unclear. Ask how faults are reported, corrected, and prevented from recurring. No supplier is flawless. Share promises in writing.

Conclusion

Choosing the right H100 server manufacturer in 2026 requires more than comparing processor counts or listed prices. Buyers should understand the server’s core architecture, including GPU configuration, CPU and memory balance, high-speed networking, storage design, cooling, power delivery, and system management. A reliable manufacturer should demonstrate strong engineering capabilities, consistent production quality, flexible configuration options, rigorous testing, and the ability to support different workloads such as artificial intelligence, scientific computing, and large-scale data analysis.

Global buyers should also evaluate total ownership cost, delivery schedules, regional logistics, warranty terms, technical support, spare parts availability, and communication efficiency. Clear quotations and dependable after-sales service can reduce deployment risks and improve long-term value. After installation, proper workload planning, monitoring, preventive maintenance, firmware management, and thermal control are essential for stable performance. Buyers should also consider future scalability, including expansion capacity, networking growth, software compatibility, and upgrade paths, so the selected H100 server platform can support evolving computational requirements.
Ethan

Ethan

Ethan is a seasoned marketing professional with a deep expertise in our company's innovative product line. With a passion for sharing knowledge and insights, he takes the lead in regularly updating our corporate blog, where he explores industry trends, product features, and effective marketing......